Early in chip design, every functional block gets a place and a shape. The inputs are the blocks, each with a target area, and the netlist of wires between them. Two objectives pull the blocks together: short wires between connected blocks and a small chip outline. A set of constraints holds them apart and pins them down. Good floorplans live exactly where these forces balance, on the edge of what the rules allow.
A floorplan is a negotiation between opposing forces
- Hard rules, must hold
- Area and no overlap. Every block keeps its area, and no two blocks may intersect.
- Fixed shape. Some blocks come with a width and height that cannot change.
- Pre-placed. Some blocks are already nailed to a spot.
- Soft rules, counted and penalized
- Clusters. Blocks of a group should touch each other.
- Multi-instance blocks. Copies of one design should share one shape.
- Boundary blocks. Some blocks must sit on a given edge of the chip.
Classical solvers such as simulated annealing face all of this inside their search, at the price of starting from scratch on every chip. Learning promises to amortize that search into a model, and a generative model fits the task: a chip admits many good floorplans rather than one, and a generator drafts complete layouts from that distribution in milliseconds.
Existing generative placers put the rules everywhere except where the model learns, and score only the end
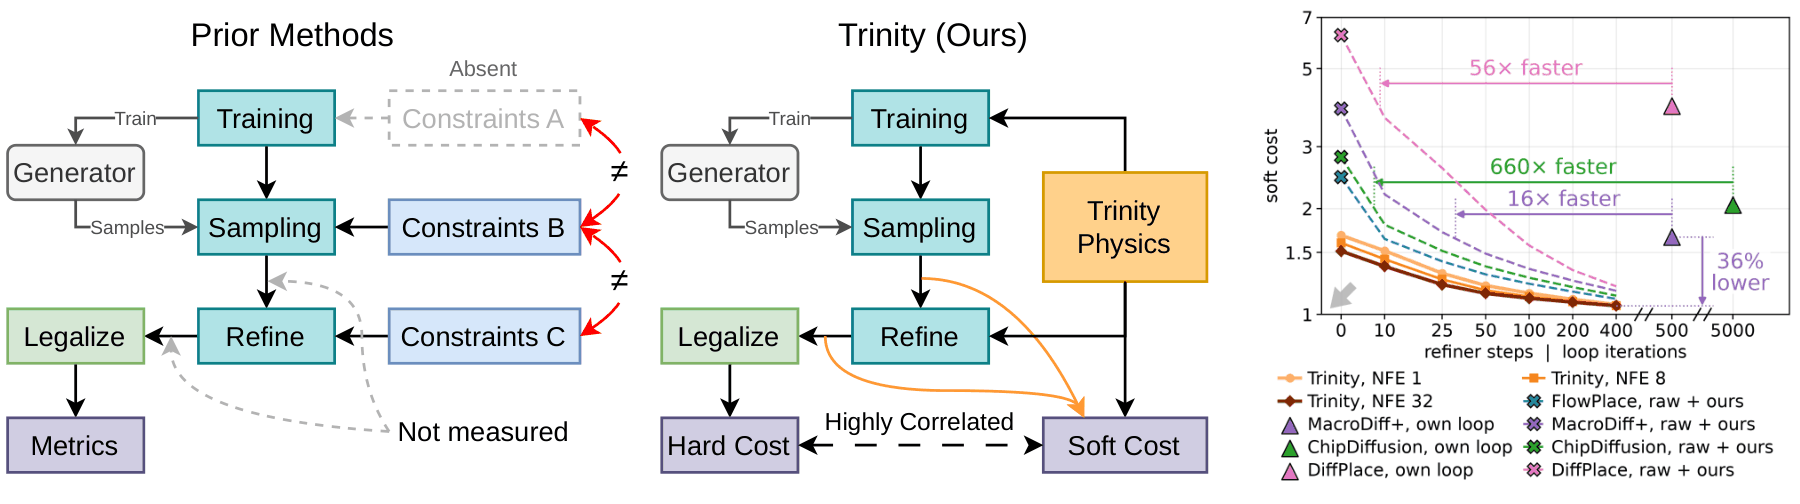
Existing diffusion placers train their networks only to reproduce reference layouts. The rules of the chip arrive afterwards, three times and in three different forms: a hand-tuned guidance term inside the sampler, post-hoc optimization loops of 500 to 5,000 iterations, and a legalizer. Compared with classical solvers, where every move faces the rules and the objectives together, the rules have migrated from the core of the search to the tail of a correction chain.
The way these pipelines are evaluated hides the consequences. Only the final legalized layout is scored, and every stage writes the rules in its own form, so the layouts in between have no common measure. A weak generator behind a strong correction looks identical to a strong generator behind a weak one, and nobody can tell what the generator contributes, or what each correction costs.
Write the rules once, as physics, and use them everywhere
Every rule of floorplanning is a geometric quantity of the layout, so each can be written as a smooth function of block positions and shapes that is zero when the rule holds: the overlap area of every pair, the gap inside each cluster, the shape spread of each multi-instance group, the distance of each boundary block to its edge, plus the wirelength and the outline area. Their weighted sum U is one energy, a physics of the layout. Trinity uses that one energy three times, the middle of the figure above.
train
A term of the training loss
The energy is added to the flow-matching loss on the network's clean prediction, so the model learns the rules together with the data instead of having them imposed after it.
refine
The energy of the refiner
After sampling, Adam descends the same energy with every gradient in closed form, about a millisecond per layout, on any generator's samples.
score
The base of a soft cost
The same quantities extend the contest's hard cost to layouts that still overlap, so raw, refined and legalized layouts finally share one scale.
The physics term is a self-supervised loss that carries the rules where the data stops
1 · What we train
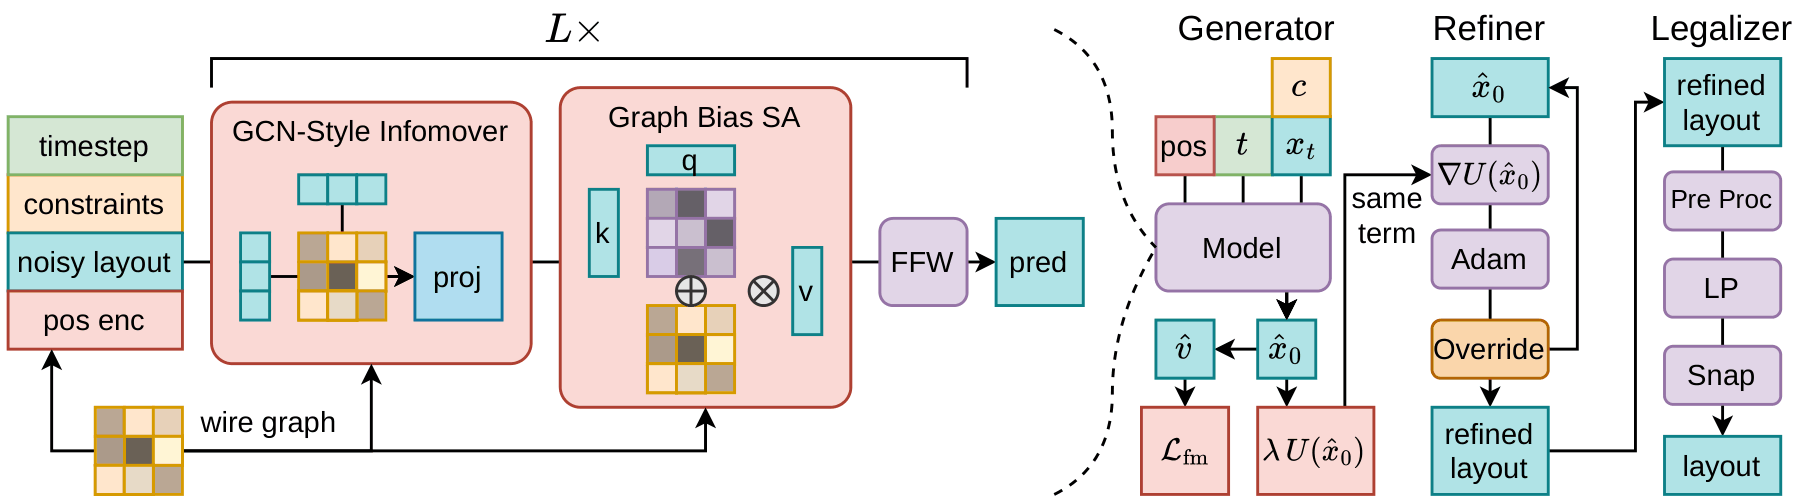
ℒ(θ) = 𝔼(c, x0) ∼ data ‖ v̂ − v(x0) ‖² + λ 𝔼 [ U(x̂0 ; c) ], x̂0 = mθ(xt, t, c)
Rectified flow with xt = (1 − t) x0 + t x1. The first term needs the reference layout x0. The second reads only the model's own prediction x̂0 and the rules of chip c; its constraint part is zero on every legal reference.
2 · A self-supervised term
The physics term has no label. Its target is the rule set of the chip, which exists for every chip, with or without an answer. On the training data its constraint part leaves the fitted data unchanged: a model trained on references alone predicts the posterior mean x̄0, and the mean of legal layouts is not legal, because legal layouts do not form a convex set. With the term, the best prediction is that mean pulled one proximal step toward the rules, strongest at high noise and gone at t = 0.
x̂0⋆ = proxγt U(x̄0) = argminm ½‖m − x̄0‖² + γt U(m), γt = λt²/2
3 · What it does where the data is silent
On a chip without a reference the flow loss has no target. The physics term still acts there, through the weights every chip shares. One training step of the term on chip c changes the violation on any other chip c′ at the rate
dU′(x̂0(c′)) / dη = −λ ∇U′⊤ K ∇U, K = Jc′ Jc⊤
J is the Jacobian of the prediction in the weights. The violation on c′ falls whenever the kernel K aligns the two rule gradients. This and the proximal step above are checked in Lean 4 (Appendix D).
The rules are local, sums over pairs of blocks and over single blocks, and the network applies the same weights to every block. That is the setting in which K is expected to align them, so a repair learned on 60-block chips can carry to 200-block ones. The data shows legality only by example; the term states the rule, and a rule transfers where examples do not.
4 · The effect, trained
A toy trained once per weight shows all three.
A trained toy: blocks as disks
1 · The data
Each training layout is a set of equal disks, the blocks, inside a square outline that grows with their number. Every training layout is legal: no two disks overlap and all stay inside. On top of the rule the data has its own taste, a compact cluster around the center. Training covers 4 to 10 disks only.
2 · Data alone
The flow-matching loss regresses the posterior mean. In one step the generator outputs that mean, and every disk lands on the center of the cloud, a pile of overlapping blocks. With 32 steps it reproduces the compact look, but the data shows non-overlap only by example and never states it: of draws are legal at 6 disks and at 10, inside its own training range.
3 · Data + physics
The rule is a sum over pairs of disks, the same at 6 disks as at 18. The term checks every prediction against it without a reference, so the network learns the rule instead of its examples: legal at 6 disks, at 10, and at 14, a size no training layout has, against without it (λ = ).
disks
in data
beyond
steps
λ (pick several)
Trained on data only
Trained with the physics term, λ = 30
Legal draws against the number of disks
The difference shows when the chips get bigger than anything in training. FloorSet chips have 21 to 120 blocks. On the GSRC benchmarks, soft blocks must fit a square outline with 10% dead space (red dashed square). Below are the best legalized layouts of the same model trained with and without the physics term, each the best of 4 seeds × 16 draws.
| GSRC case | With physics (Trinity) | Without physics (λ = 0) | PARSAC WL | ||||||
|---|---|---|---|---|---|---|---|---|---|
| WL (mm) | W × H | Dead space | Draws fit | WL (mm) | W × H | Dead space | Draws fit | ||
| n100, outline 444 × 444 in range | 294.7 | 433 × 423 | 2.1% | 36% | 293.9 | 444 × 413 | 2.0% | 80% | 303.5 |
| n200, outline 440 × 440 beyond | 554.9 | 434 × 407 | 0.7% | 100% | 560.1 | 440 × 498 | 19.8% | 0% | 576.0 |
| n300, outline 548 × 548 far beyond | 681.3 | 708 × 448 | 13.8% | 0% | 679.8 | 648 × 503 | 16.2% | 0% | 705.2 |
Best legalized layout over 4 seeds × 16 draws (NFE 8, 400 refiner steps). W × H is its outline against the 10% dead-space square; red marks an outline that does not fit. At n300 no draw fits, so the row shows the best legal layout. FloorSet training chips have 21 to 120 blocks.
Inside the training range the two models tie (n100: 294.7 against 293.9 mm), as expected when the data already covers the case. At 200 blocks, almost twice the largest training chip, the physics term is the difference between a floorplan that fits with 0.7% dead space and one that cannot fit at all, at shorter wirelength too. At 300 blocks neither fits. That residual is a known open problem of transformer generators on sizes far beyond training, not of the physics, and it is where we see the next step.
5 · Beyond floorplans
Nothing in the argument is specific to chips. Any diffusion or flow model can add a reference-free term on its own prediction x̂0. It helps when the term is zero on the data, computable on x̂0, and built from local parts that shared weights can carry: collisions and valence for molecules, steric clashes for proteins, equation residuals for physical fields, foot contact for motion. Its weight needs tuning: in the toy, λ = 30 is best beyond the data at 16 and 32 steps, while λ = 100 overshoots there and helps only at 8.
With one scale, every stage shows what it contributes
We re-implemented four existing diffusion placers, FlowPlace, ChipDiffusion, MacroDiff+ and DiffPlace, on the same data and training recipe, and scored every model at every stage on 12,000 held-out FloorSet chips with the soft cost.
The physics term improves every rule of the raw samples
Same plain transformer, physics term on (λ = 0.01) versus off: reduction of each quantityA usable floorplan from one network call
Soft cost of raw samples against sampling steps (log scale, lower is better)Our refiner against each placer's own loop, from the same raw samples
Soft cost against refinement steps or loop iterations. Lines: our refiner on each generator. Triangles: each placer's own loop at its released iteration count. Log scales.Three things become visible. The training term governs the start: it lowers raw soft cost and keeps Trinity ahead at short refinement budgets. The refiner governs the end: after a few hundred steps every generator converges near one value, and each one ends below where its own loop leaves it, reaching that loop's cost 16 to 660 times sooner. So generators should be compared under one shared refiner; under their own loops, the loops drive most of the gap. And the soft cost ranks settings the way the contest's hard cost does (Spearman 0.94), so these budgets can be chosen without running the legalizer.
Legal floorplans, fast
After legalization
Hard cost of the first legalized draw: each generator with its own loop versus with our refiner1.014
mean hard cost on the FloorSet validation set, best of 48 draws
1.63 s
per chip on one GPU, legalization in parallel
−36%
refined soft cost against the best existing pipeline
≈1 ms
per layout for 400 refiner steps in a batch
More chips. The full pipeline on three FloorSet validation chips.
What we hope carries over
Measure every stage, not just the end
The endpoint of a correction chain hides who did the work. With one scale for raw, refined and legalized layouts, the generator's contribution becomes visible.
Put the physics where the model learns
A rule in the training loss becomes a correction the network performs for free, strongest when noisy and gone when clean. A rule in the sampler is a cruder substitute that keeps pushing on good layouts.
Compare generators under one refiner
Under a shared refiner generators converge, while their own loops differ widely. Most reported gaps between pipelines come from the loops.
Choose budgets before the expensive step
The soft cost ranks settings the way the legal hard cost does, so sampling and refinement budgets can be tuned without running the legalizer.
BibTeX
@misc{trinity2026,
  author = {Yeh, Shih-Ying and Wang, Tzu-Sian and Wang, Xuehai and Lee, Jia-Hua and Kaplan, Daniel Z. and Xu, Ming-Qi and Tang, Wuqian and Wang, Chun-Yao and Lai, Shang-Hong and Lee, Chun-Yi},
  title = {{Trinity: One Differentiable Physics for Training, Refining and Scoring Generative Floorplanners}},
  year = {2026},
  eprint = {2610.04957},
  archivePrefix = {arXiv},
  primaryClass = {cs.LG},
  url = {https://arxiv.org/abs/2610.04957},
  note = {arXiv preprint}
}